
Blog
11.3.26
Agents Are the New Operating System. Nobody Knows What’s Installed
Galina Antova
Co-Founder & CEO


The question we skipped
Every conversation I had about agent security for the last year had the same shape. Should agents be allowed to touch production? What guardrails, what approvals, what scope? Serious people, serious debate, real stakes.
And while that debate ran, agents were being extended. Not by security teams. By developers, by analysts, by finance, by anyone who found a skill that did something useful and installed it, because installing it took about four seconds and did not look like a software procurement decision.
So the debate about future authority was happening on top of an installed base nobody had inventoried.
This is the part I find genuinely uncomfortable, and I say that as someone whose company builds on this technology. We were arguing about the front door while the extension mechanism was wide open, and the extension mechanism is the more interesting attack surface — because it is the one that scales.
Why skills are an operating system problem
The word “skill” does the industry a disservice. It sounds like a setting.
What a skill actually is: third-party content, often authored by someone you cannot identify, that is loaded into the context of a system with tool access, credentials, and the authority to act on your behalf. It can carry instructions. It can carry code. It executes inside a trust boundary that was drawn around the agent, not around the skill.
That is not a plugin. That is closer to installing a kernel module.
Operating systems took decades to build the machinery this implies: package signing, provenance, dependency inventory, a patch channel, a revocation path, an install log you can audit. Every one of those exists because someone learned the hard way that a general-purpose extension mechanism without them is an unbounded liability.
The agentic ecosystem has the extension mechanism. It is still building most of the rest. And it has gone from zero to enormous installed base in roughly the time it takes an enterprise to complete one procurement cycle.
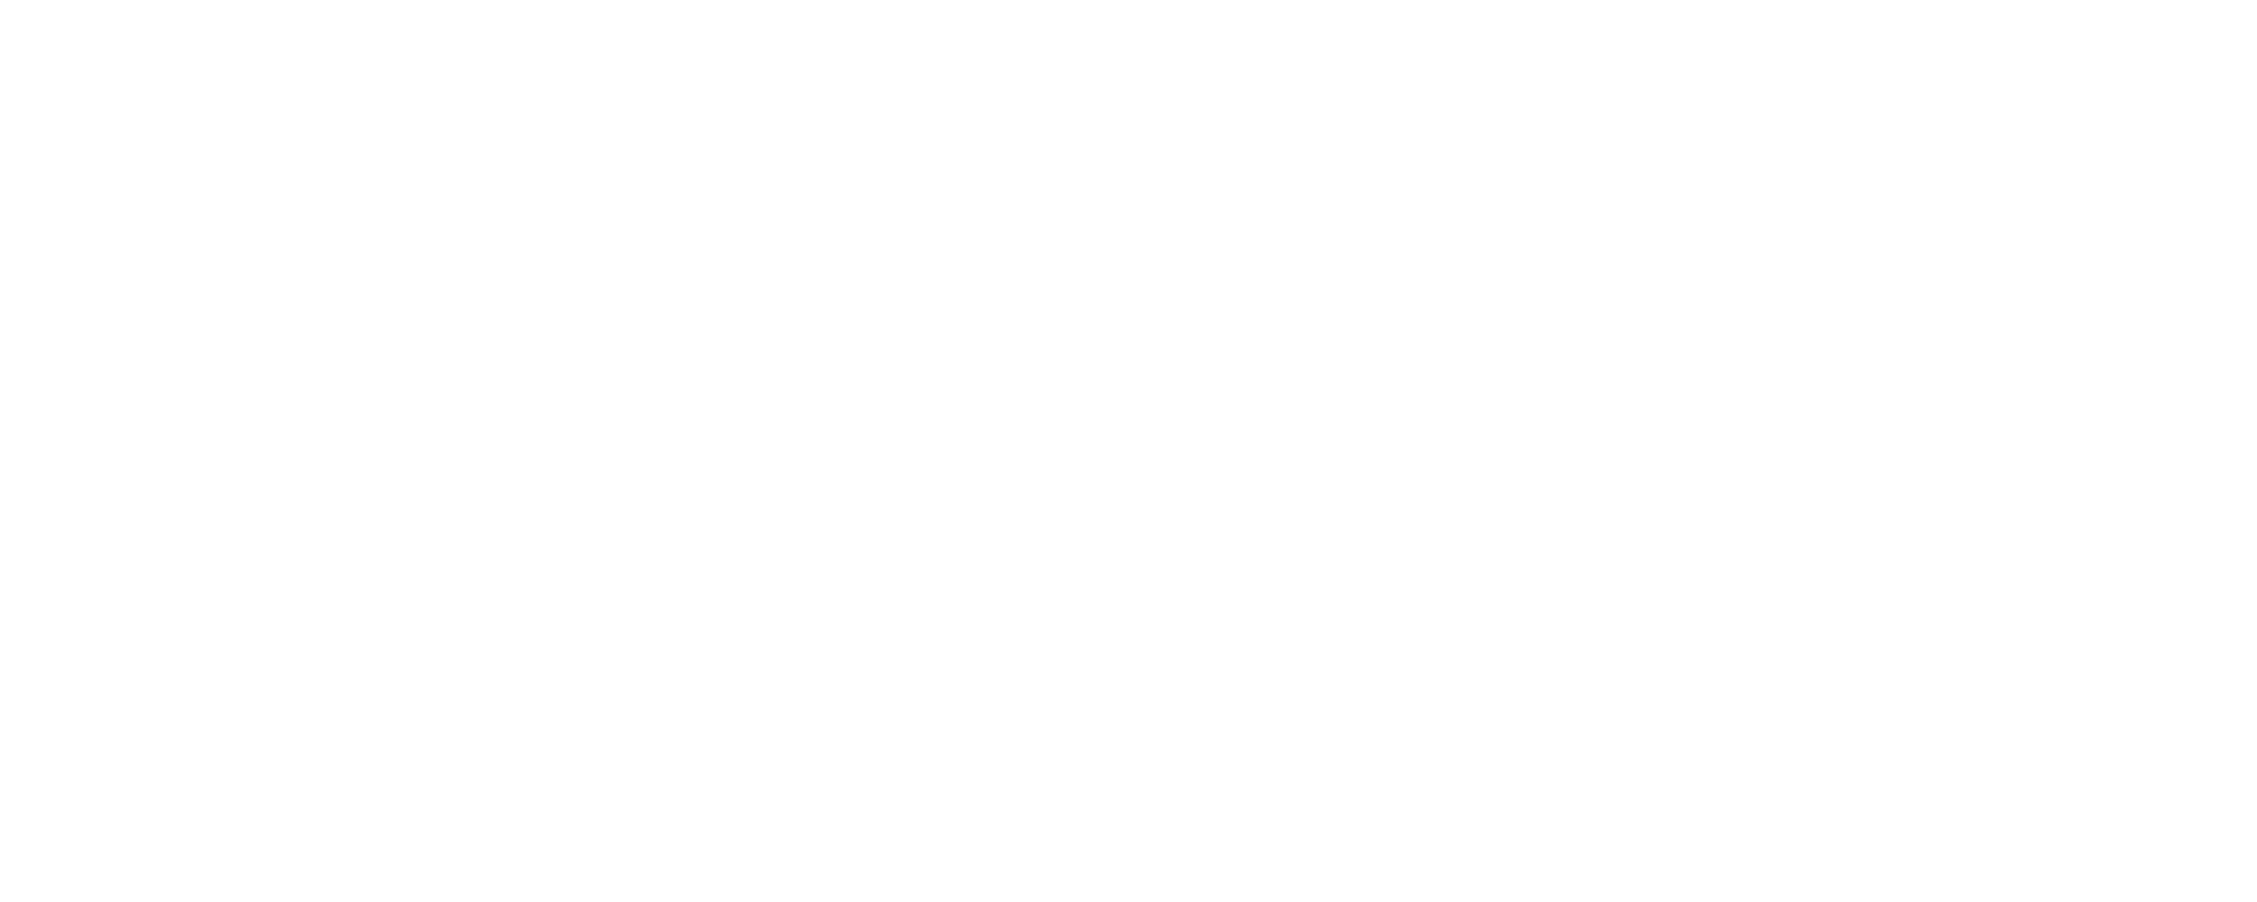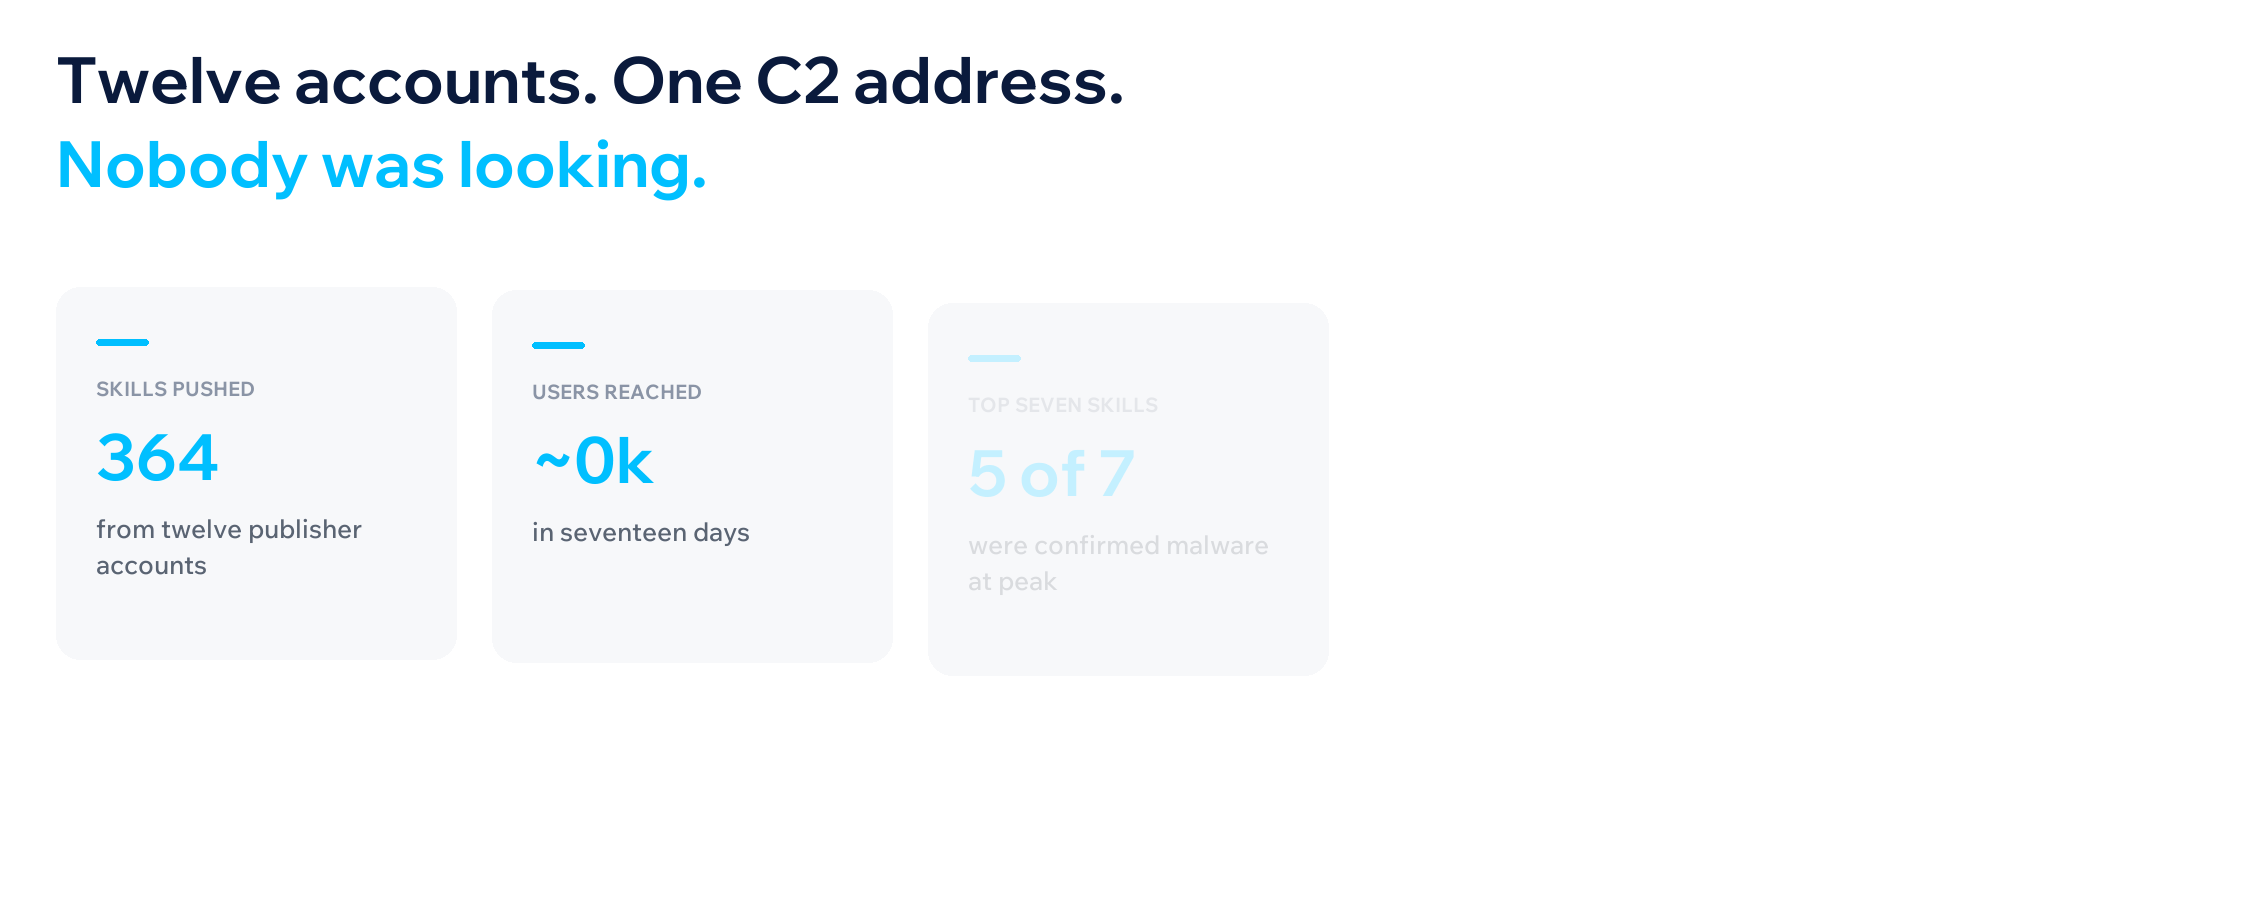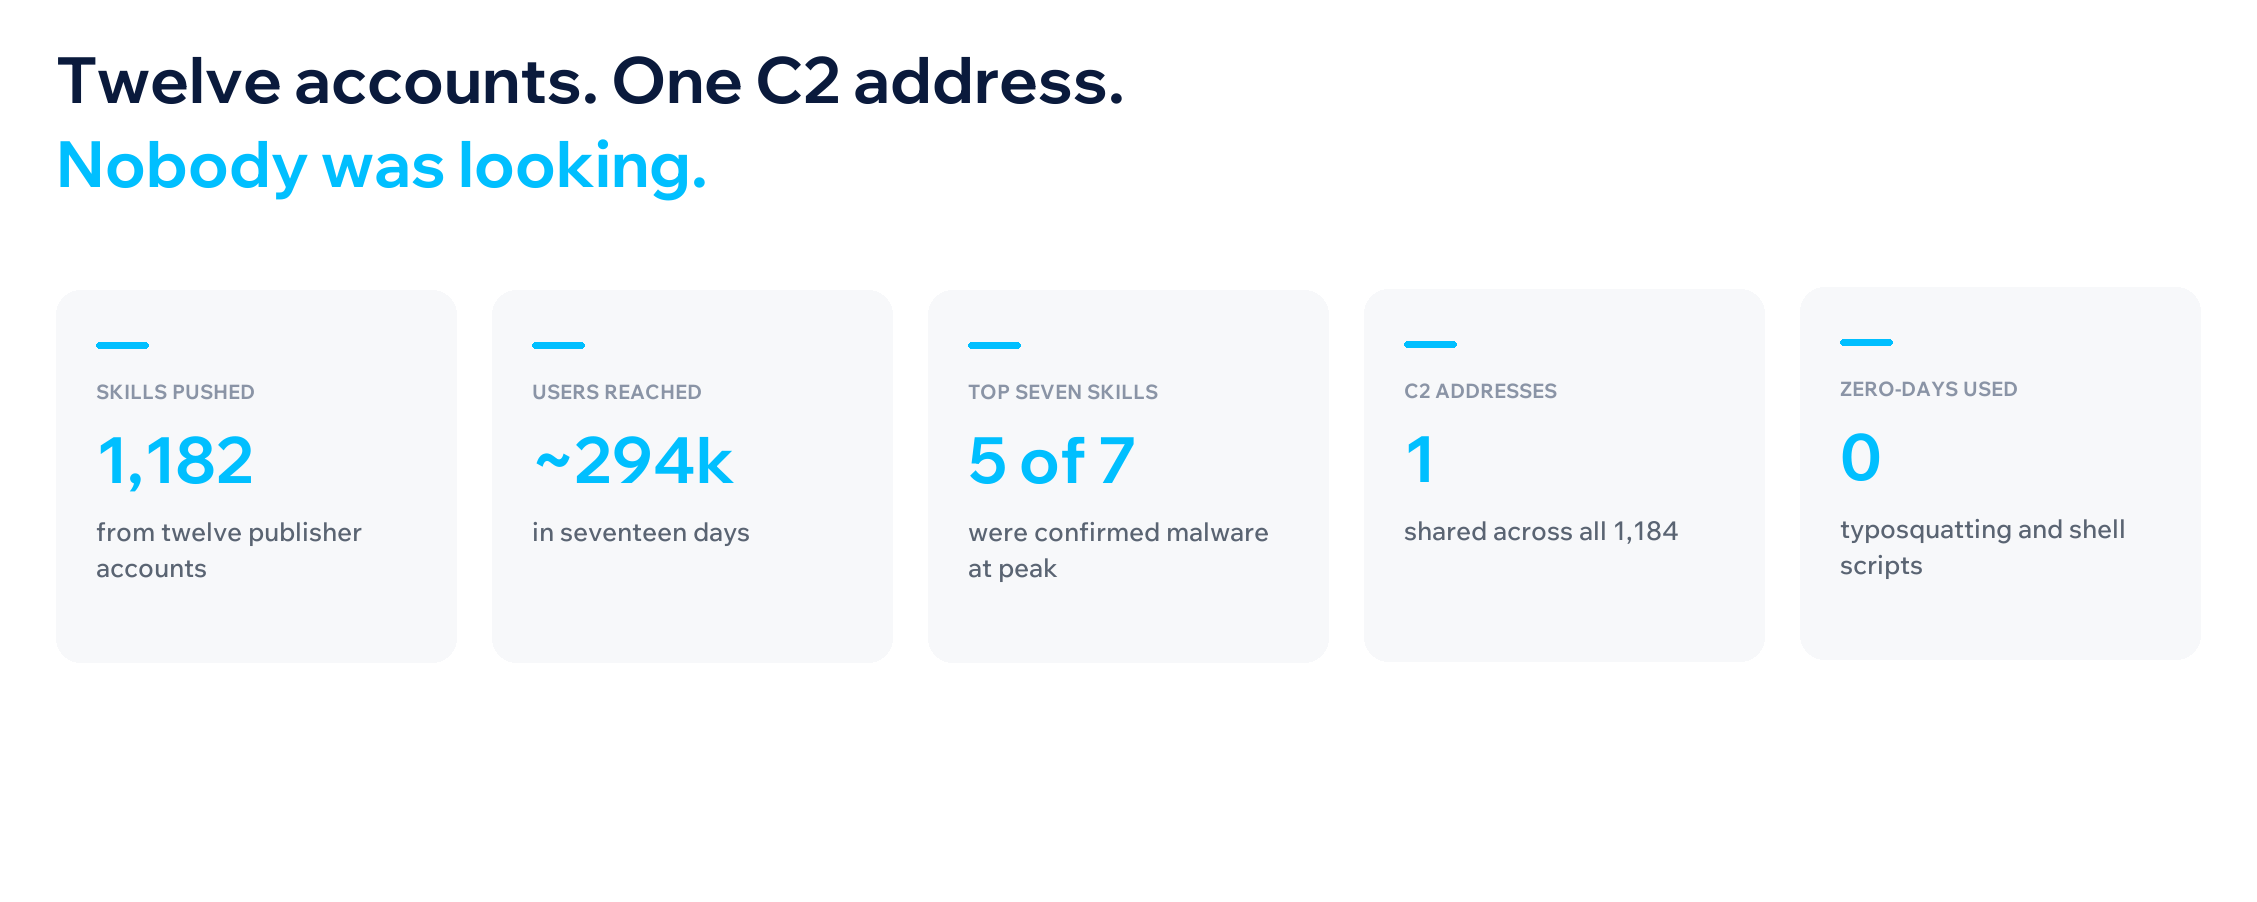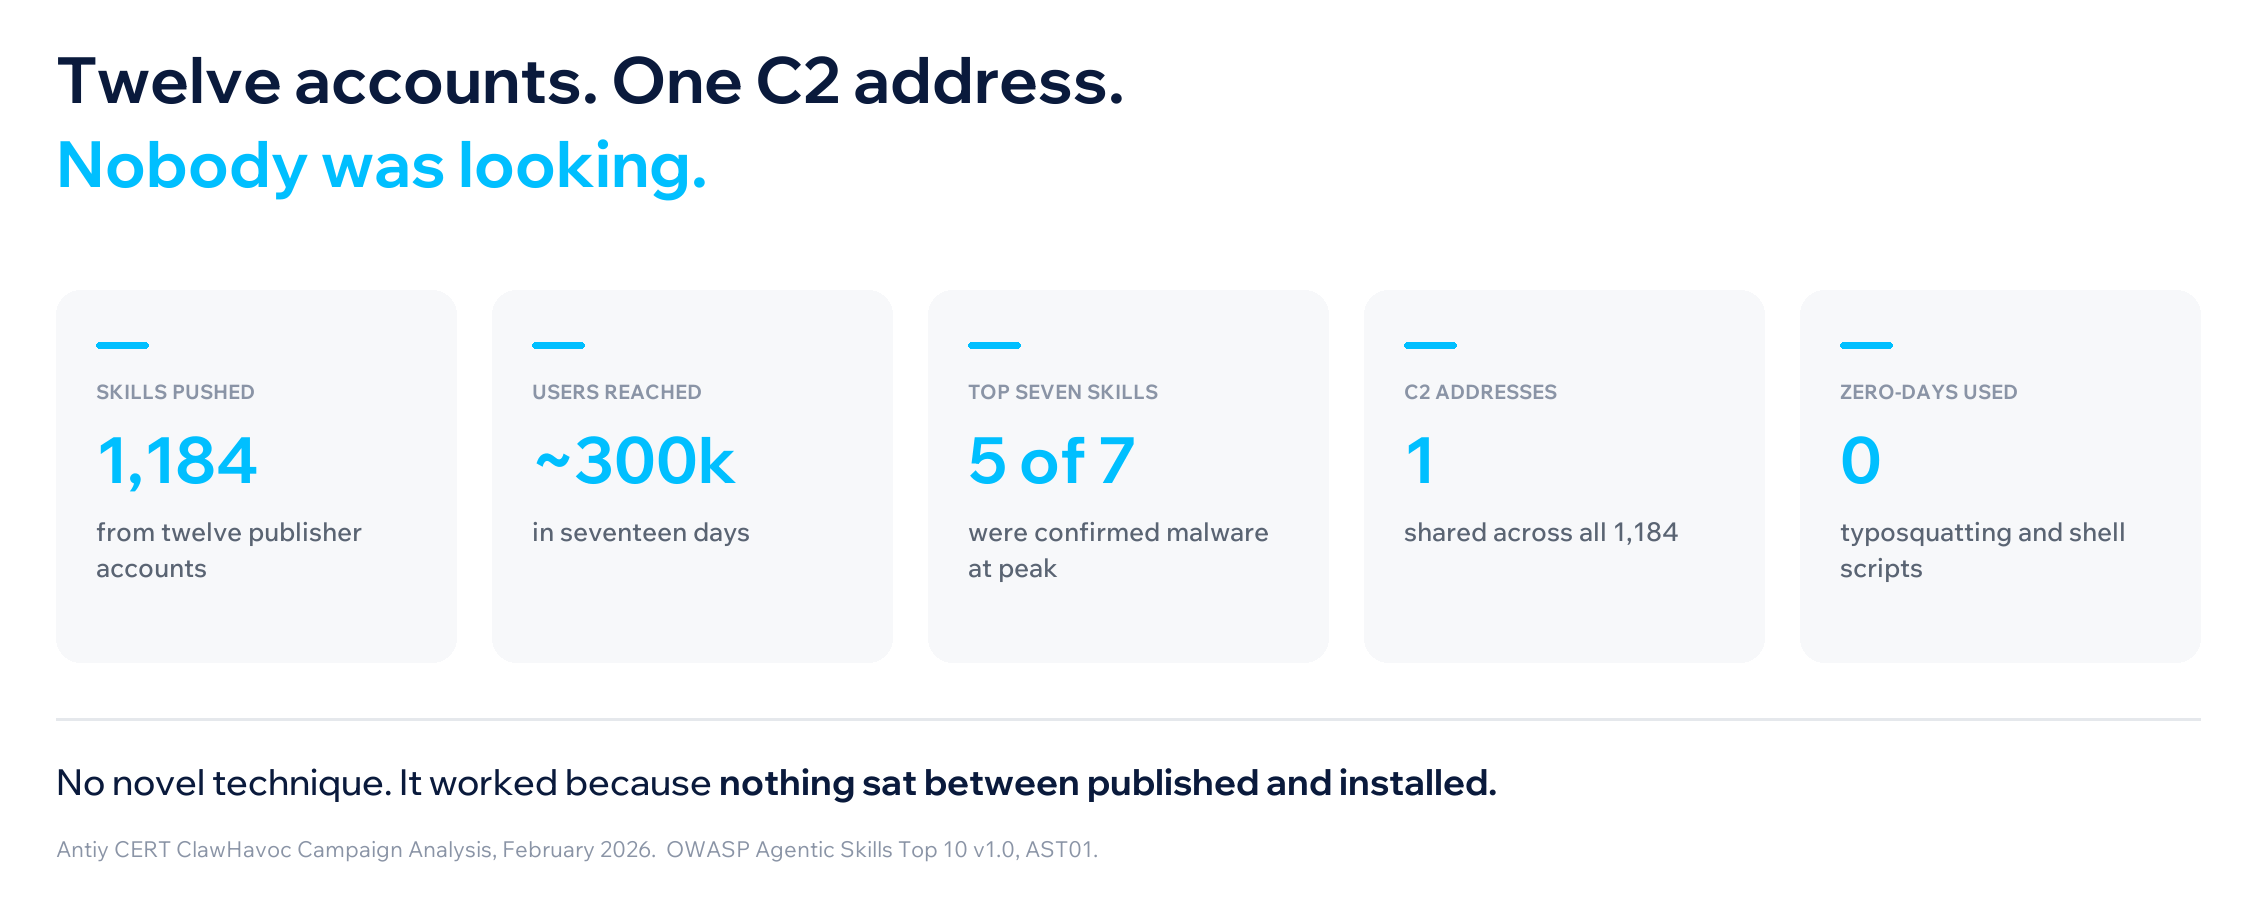
ClawHavoc is instructive precisely because it was not sophisticated. Read Antiy CERT’s analysis and the tradecraft is almost dull: twelve publisher accounts, 1,184 skills typosquatting legitimate names, a dual-layer payload pairing markdown instructions with an embedded shell script, and an Atomic Stealer variant going after macOS crypto wallets, SSH keys and browser credentials. Every one of those skills called home to the same C2 address.
One IP. Eleven hundred skills. Seventeen days, roughly 300,000 users, and at peak the majority of the most popular skills in the registry were malware.
No zero-day. No novel technique. Not even operational hygiene on the attacker’s side — a single shared C2 is the kind of thing that gets a campaign rolled up in an afternoon once anyone is looking. It worked because nobody was, and because there was no provenance layer between “published” and “installed.”
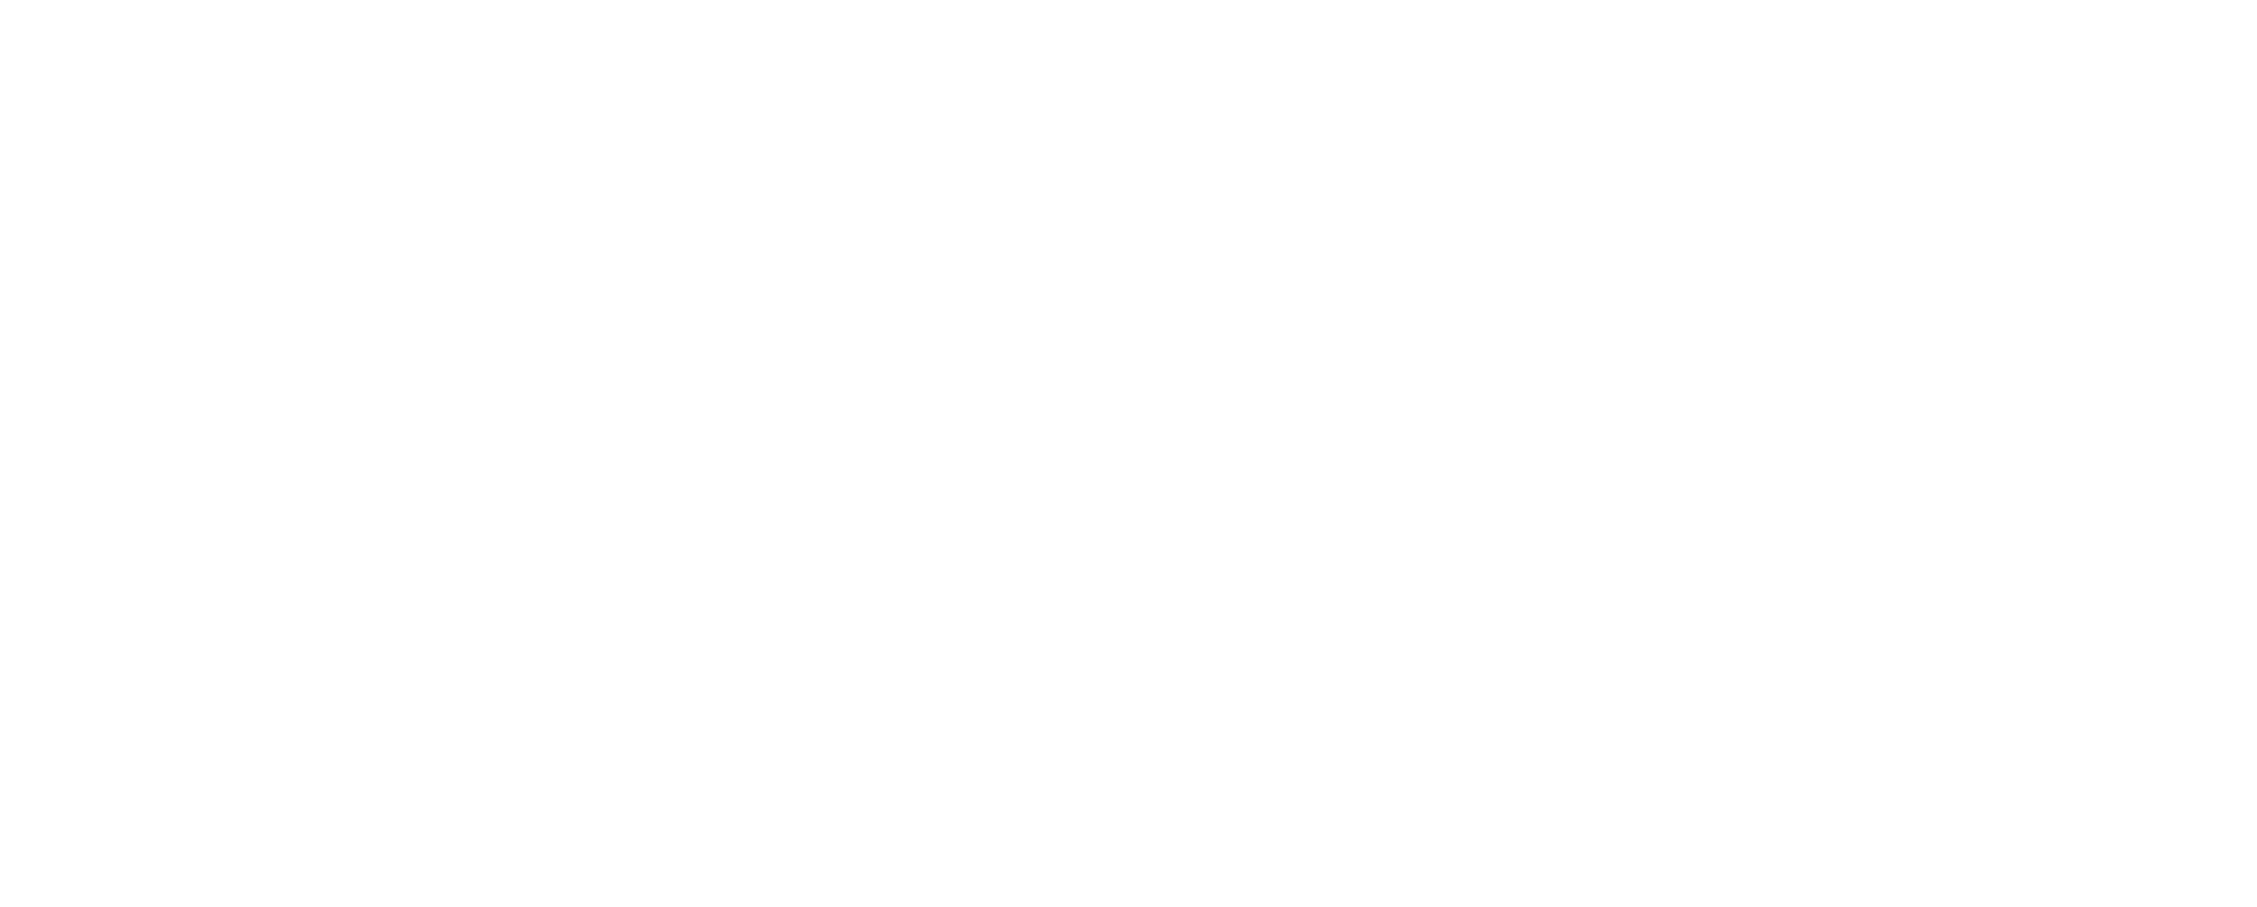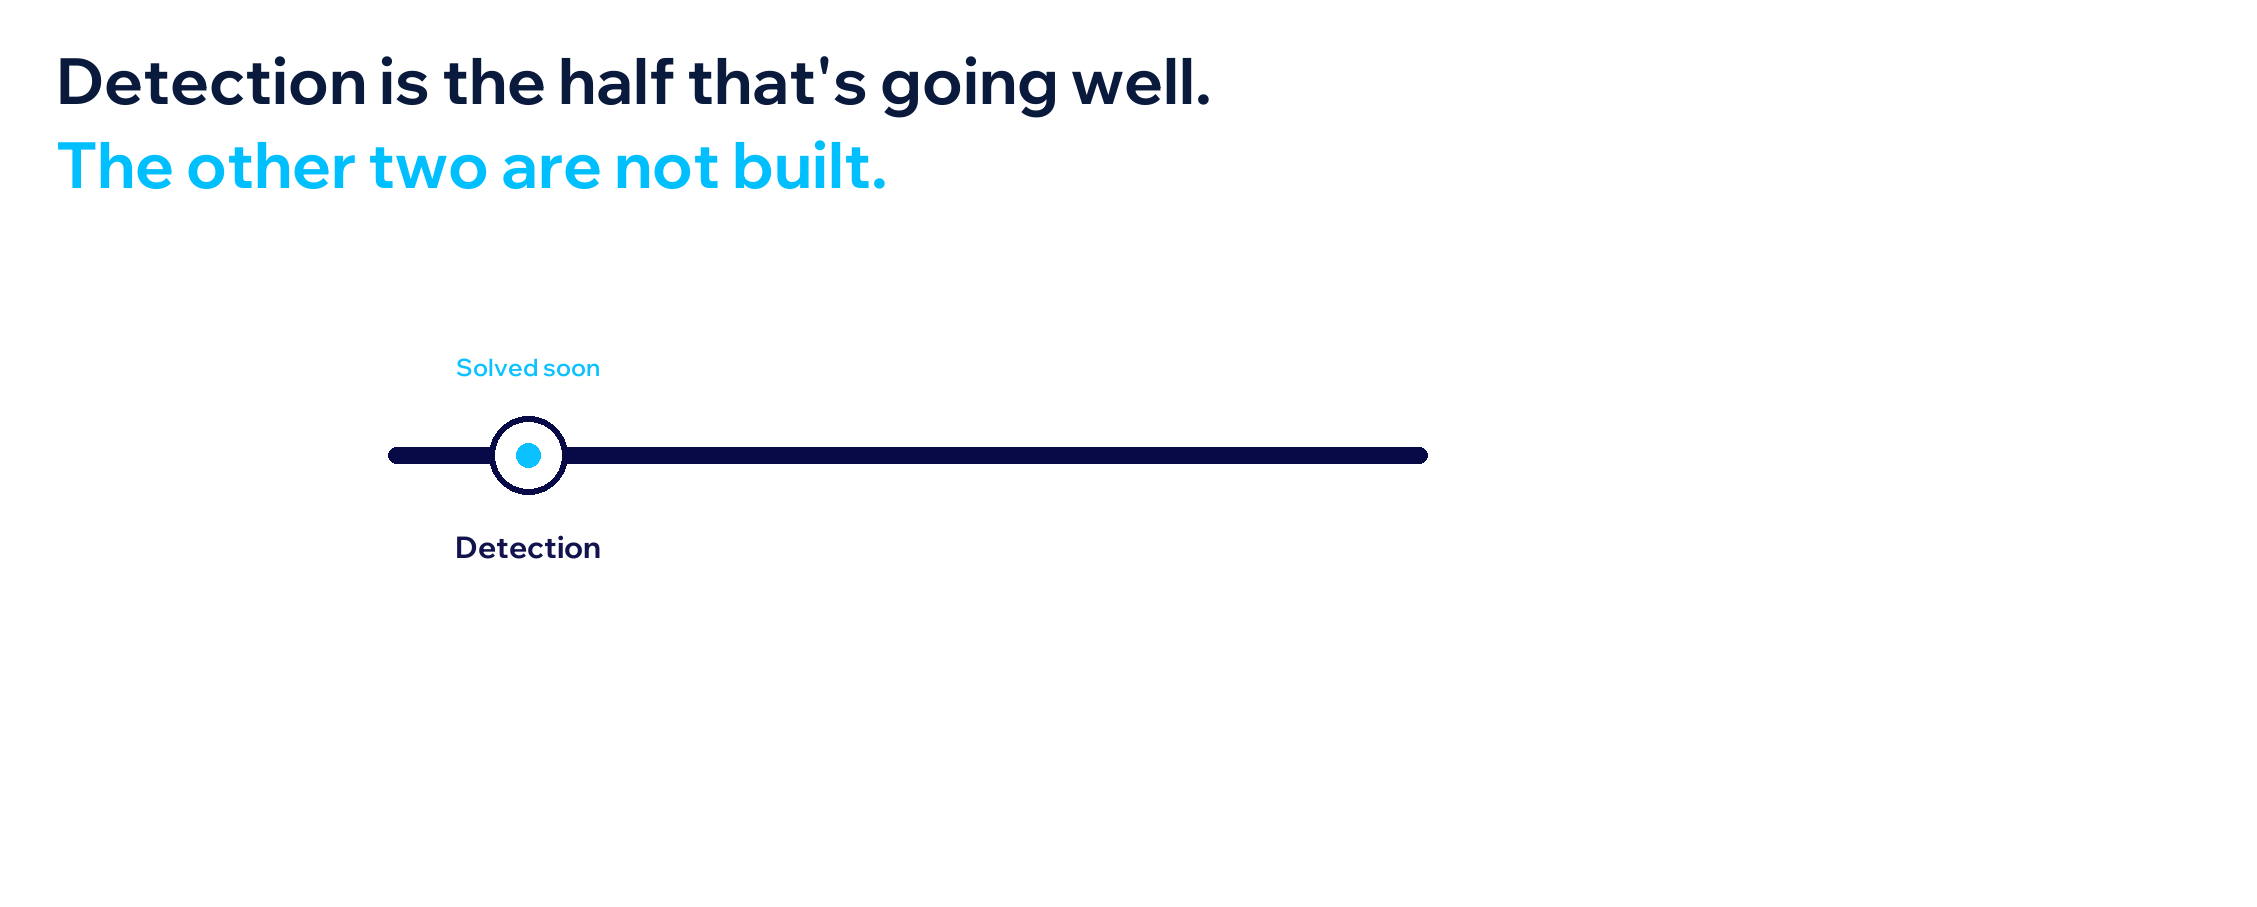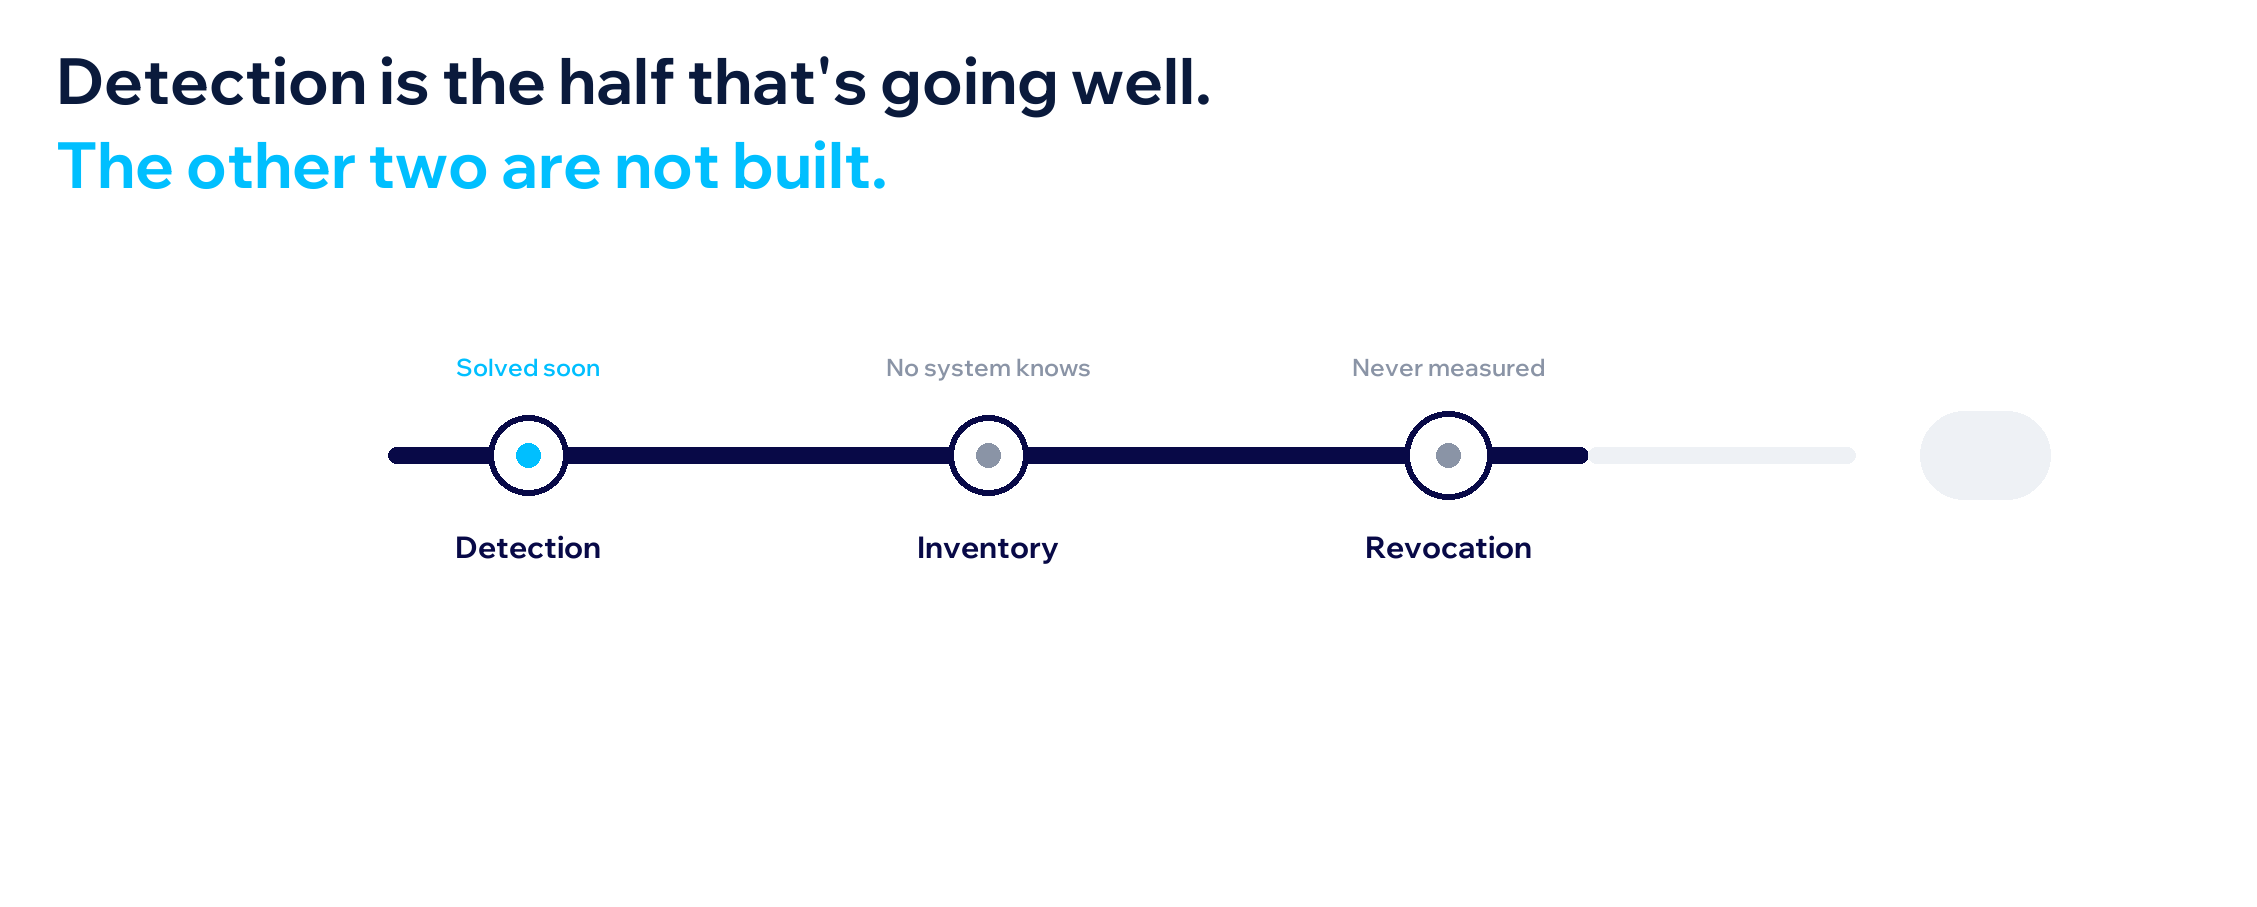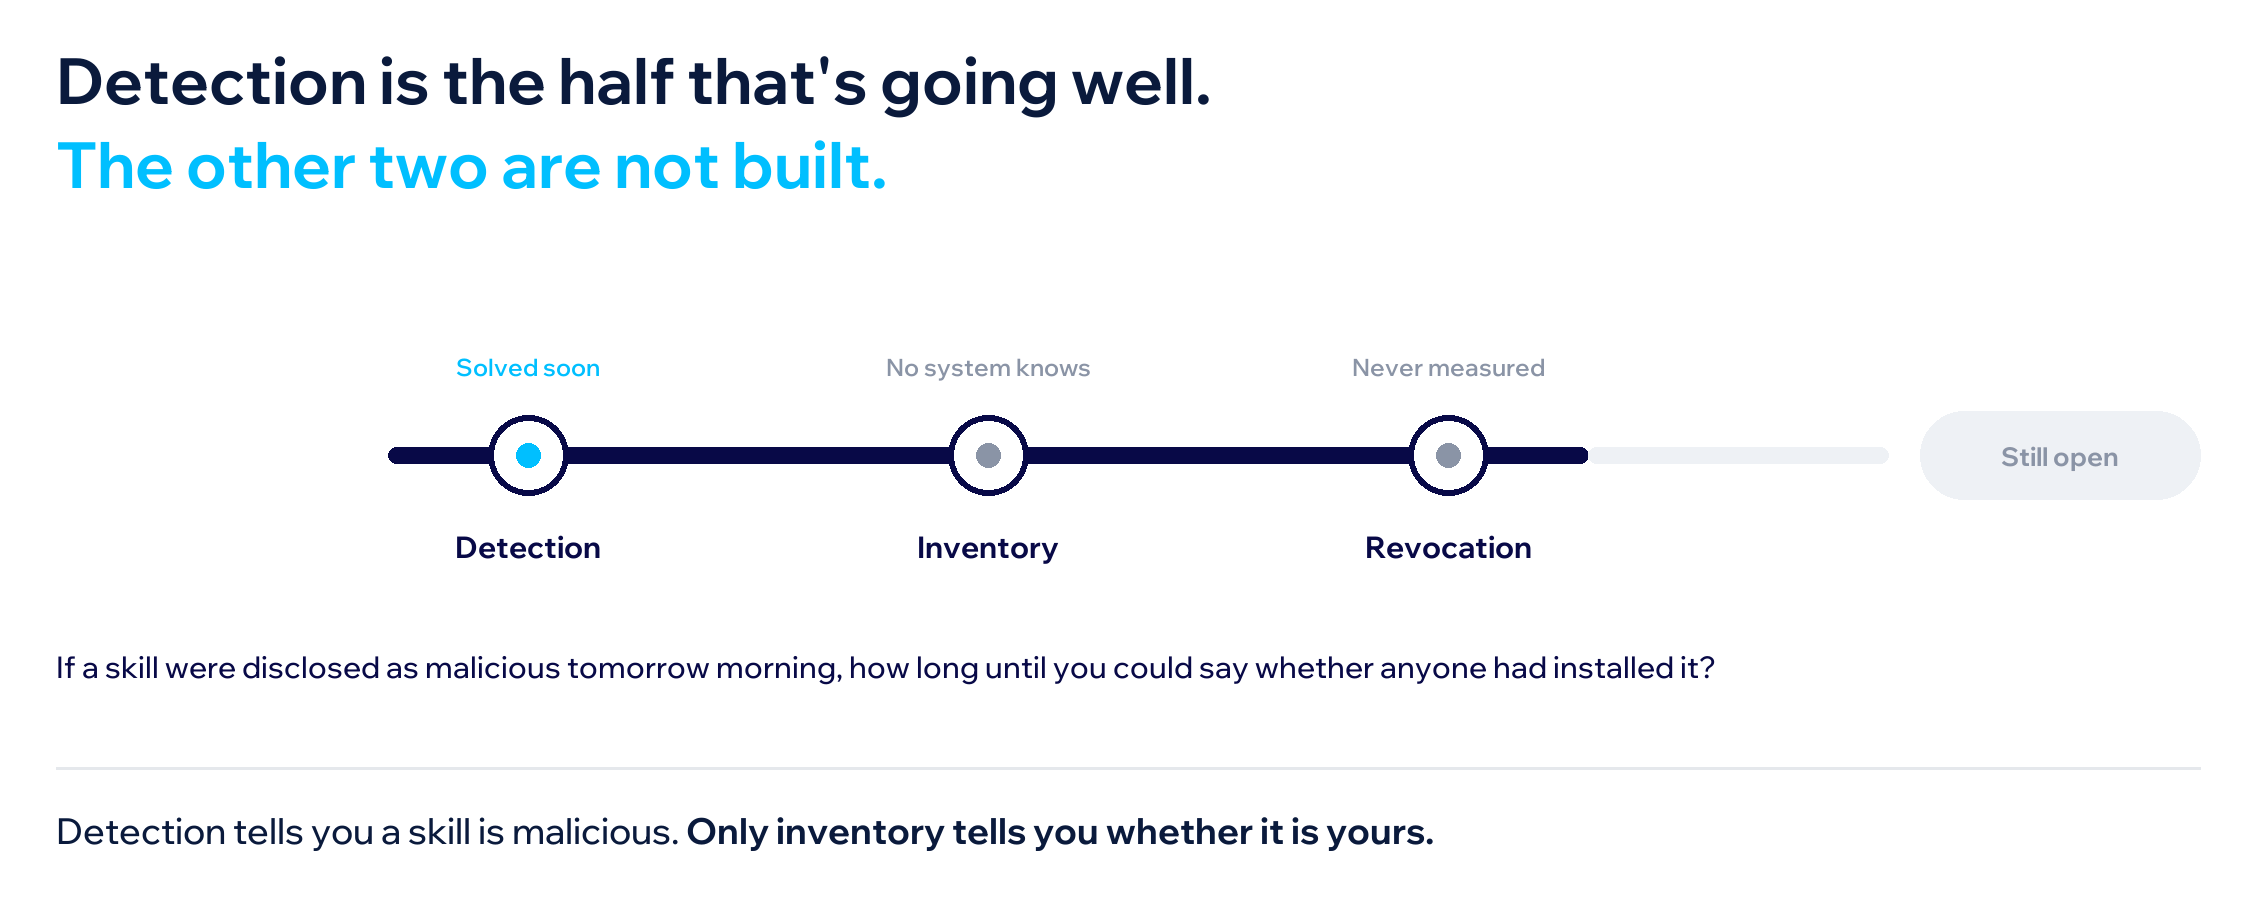
Detection is the half that’s going well
I want to give credit where it is due. The detection side is moving fast.
OWASP shipping a ranked, specific taxonomy within a year of the risk becoming real is a genuinely good outcome — that is much faster than the equivalent turnaround for cloud or for containers. Registries are adding scanning. Vendors are building classifiers. The research community is publishing. Within a year I expect identifying a malicious skill from its content to be a largely solved problem.
Which is why I want to be blunt about where the difficulty actually moves.
Knowing a skill is malicious is a detection problem. Knowing whether it is in your environment is an inventory problem. Getting it out of every place it is installed, quickly, and proving you did, is a throughput problem. Those are three different capabilities and the industry is only good at the first.
Ask the honest version of this question inside your own organization: if a skill were disclosed as malicious tomorrow morning, how long until you could say with confidence whether anyone in the company had installed it? For most organizations the answer is that there is no system that knows. Installs happened on individual machines, in individual accounts, through individual registries, with no central record. You would be sending an email and hoping.
Now ask the second question: how long to revoke it everywhere? And the third: what did it do while it was there?
This is the throughput gap, with a worse clock
The structure of this problem is one I have written about repeatedly in a different context, and it is worth naming the symmetry.
In vulnerability management, the fix almost always exists. The gap is execution — dependency resolution, testing, approvals, release queues. Knowing is not the constraint; closing is.
Agentic skills have exactly the same shape. Disclosure will be fast. Detection will be fast. The gap between “this is known to be malicious” and “this is no longer running anywhere in my environment” is the whole risk, and it is governed by inventory quality and revocation capacity — neither of which most organizations have built.
Except the clock is worse here in two ways. A vulnerable library sits there until someone exploits it; a malicious skill is already executing, with credentials, on a schedule. And the install surface is not your servers. It is every laptop and every account where someone found a skill useful.
Autonomy without deterministic validation is a new attack surface
I would like this to be treated as an architectural principle rather than a line in a deck, so let me state it as precisely as I can.
An agent’s value comes from acting without asking. That is the entire point; an agent that checks in before every step is a very expensive form of autocomplete. But the authority to act without asking is only safe if something deterministic sits between the input and the action — something that validates what is about to be executed, independent of the reasoning layer that decided to execute it.
A skill is input. It is untrusted content entering a system with execution authority. If the only thing standing between that content and action is the agent’s own judgment about whether the content looks legitimate, you do not have a control. You have a reasoning layer evaluating its own inputs, which is the arrangement that fails every time it is tested.
The same principle governs whether you can trust an automated fix, and it governs whether you can trust an installed skill. Validation has to be deterministic, external to the reasoning layer, and it has to produce evidence. Everything else is preferable.
Where to start
Inventory first. You cannot revoke what you cannot enumerate, and enumeration is unglamorous, tractable work you can start this quarter. What agents are running, under whose identity, with what skills loaded, from which registries, with what credentials.
Then provenance. Allowlist registries. Require signed and attributed skills for anything with tool access. Treat an unsigned skill the way you would treat an unsigned kernel extension.
Then revocation as a capability you have actually tested. Not a documented procedure — a rehearsed one, with a measured time-to-revoke. That number is your real exposure window, and I suspect most organizations have never measured it.
We spent a year asking whether we should trust agents with production access. The more useful question was always what is already inside them. Detection will tell you a skill is malicious. Only inventory tells you whether it is yours, and only throughput gets it out.

